
Google says Gemini’s new agentic video understanding can dynamically search frames, audio, and transcripts instead of sampling a video at one fixed rate. That could make AI video analysis more efficient, but vendor benchmarks do not tell you whether a model finds the one moment your edit depends on. A useful audit hides a ground-truth event set, runs identical questions in static and agentic modes, and prices mistakes as well as tokens.
Turn verified video findings into an APOB storyboard brief
Google’s September 1, 2026 announcement reports benchmark improvements of up to 88% fewer tokens, up to 66% lower analysis cost, and up to 7% higher accuracy for supported Gemini models. Those are Google’s “up to” results, not APOB results and not guaranteed savings on your footage. The protocol below produces a dated, file-specific receipt instead of repeating the headline.
Treat this as a video content analysis regression test. It compares two processing modes on one controlled file; it does not compare Gemini with every other model or prove suitability for every genre.
Plant a ground-truth event set
Create a 20-minute video you own. It should be ordinary enough to represent your work and structured enough to score exactly. Hide the answer key from the operator until both runs are complete.
Moment retrieval
Plant four brief state changes: a light switches color, a label rotates toward camera, a timer reaches zero, and a hand swaps two objects. Record the first and last frame of each event. At least one should last less than a second so fixed-rate sampling faces a real challenge.
Place events far enough apart that their evidence windows do not overlap. That makes it possible to score retrieval precision and identify when a broad answer includes the right moment by accident.
Action count
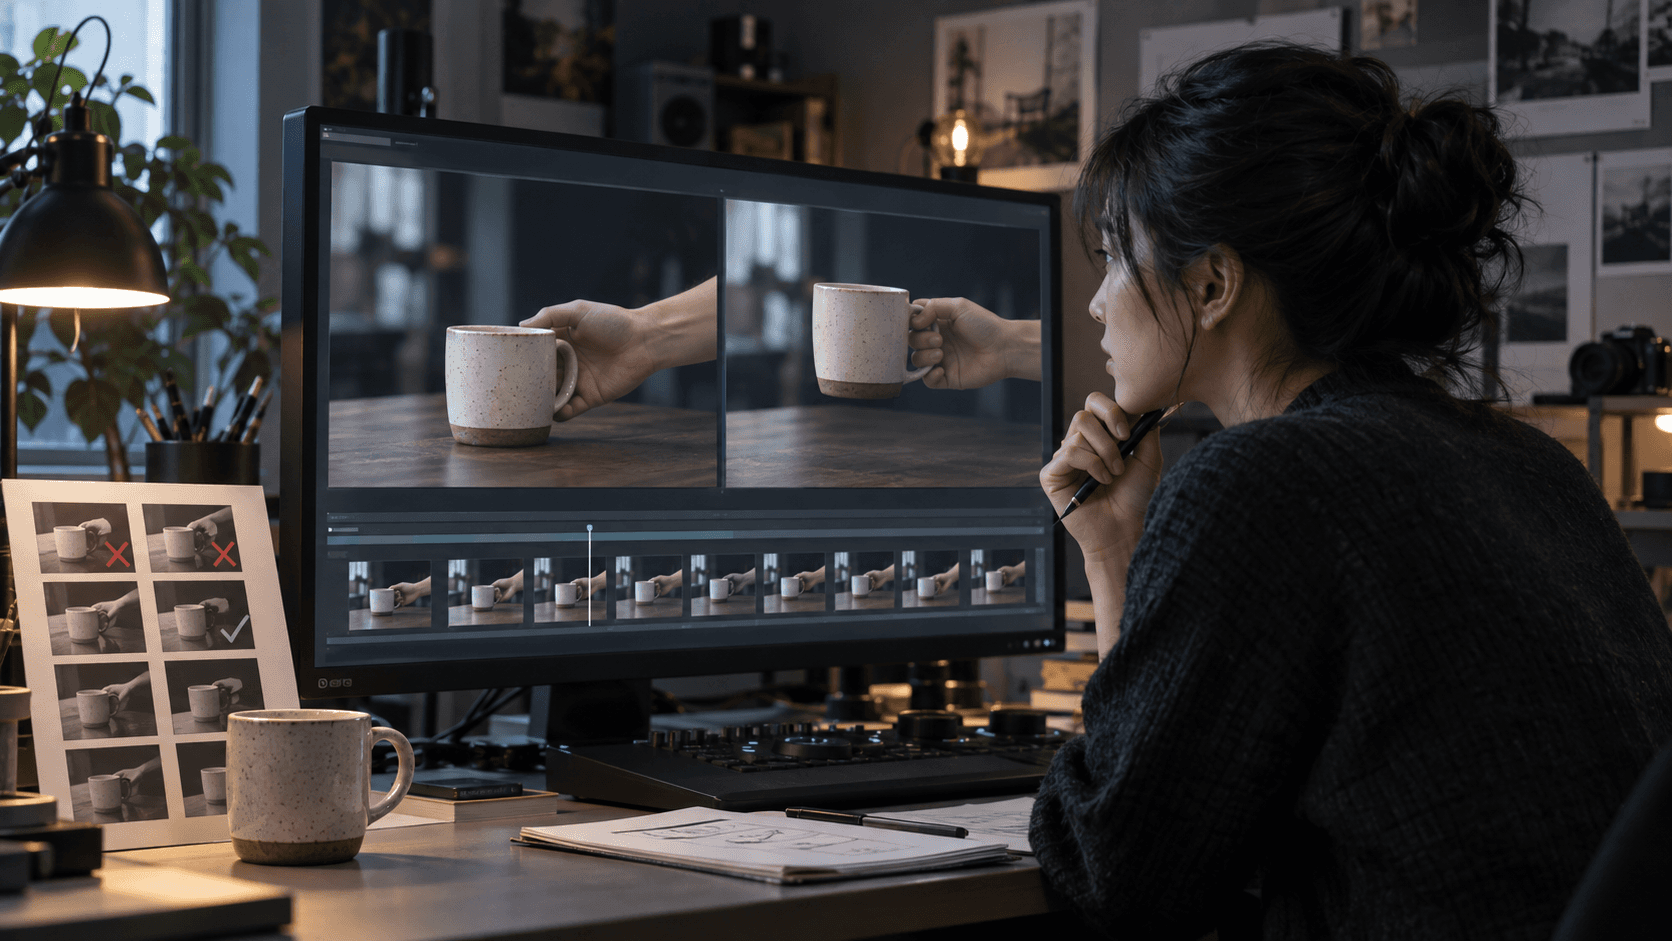
Repeat a visible action with controlled spacing, such as placing a cup on a table nine times. Include two fast repetitions and one near-action that does not complete. The answer key should define what counts before analysis begins.
Record a manual tally with timecodes. The tally, not the author’s memory, is the ground truth against which the AI video analyzer is scored.
Audio-only fact
Speak one fact while the relevant object is off-screen: The blue case belongs to order 418. Put a different number in an on-screen transcript trap later. This tests whether the system uses audio, transcript, and visual context appropriately.
Anomaly window
Insert one short anomaly: a product label reverses for eight frames or a prop moves between otherwise matched cuts. Record its timecode and visual boundary. Do not include a clue in the filename.
Event ID | Type | Ground truth | Start | End | Decoy/near miss |
|---|---|---|---|---|---|
E01 | Moment | Light changes amber to blue | ___ | ___ | Reflection only |
E02 | Count | 9 completed placements | ___ | ___ | 1 incomplete move |
E03 | Audio-only | Order 418 | ___ | ___ | Transcript shows 481 later |
E04 | Anomaly | Label reversed | ___ | ___ | Normal rotation |
Store the manifest separately and hash both video and answer key. The operator receives only the video and query sheet.
Keep the source master, upload copy, transcript, and event sheet under stable identifiers. If the service creates a proxy, note that fact so later timestamp differences can be traced to the correct file rather than attributed automatically to the model.
Ask the same six questions two ways
Use the same Gemini model, file, account, region, temperature, response schema, and questions. Change only processing mode. Google’s agentic video announcement describes agentic processing as dynamically deciding what to inspect; the developer guide is the configuration source to check before running.
Static baseline
Run the six locked questions with static processing. Record model identifier, sampling configuration, file reference, prompt, response, input/output tokens, cost, latency, and any warnings. Do not adjust the prompt after a wrong answer.
Questions:
At what exact time does the light first become blue?
How many complete cup placements occur?
What order number is spoken for the blue case?
During which time window is the label reversed?
What evidence supports the order-number answer—visual, audio, transcript, or more than one?
Which answer is least certain, and why?
Agentic run
Repeat with agentic processing enabled according to the current API documentation. Capture tool calls or inspected windows when the interface exposes them. Do not give the agentic run hints derived from the static failure.
Use the same upload or file URI lifecycle for both modes. Re-encoding one input but not the other could change timestamps and make the Gemini video understanding comparison invalid.
Query lock
Hash the question list and use the same response format: answer, timestamp/window, evidence modality, confidence, and supporting observation. A wording change can alter behavior and would turn the comparison into two different tasks.
Run log
Record each request, response, tokens, cost, latency, inspected segments, errors, retries, and date. Google currently says agentic video understanding is available across Gemini 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite; record the exact model used rather than citing the family.
Field | Static | Agentic |
|---|---|---|
Model/version | ___ | ___ |
Processing config | ___ | ___ |
Query hash | ___ | ___ |
Input/output tokens | ___ | ___ |
Cost | ___ | ___ |
Latency | ___ | ___ |
Errors/retries | ___ | ___ |
Score retrieval, counting, and context
Reveal the answer key only after both receipts are frozen. Two reviewers score independently. Publish wrong answers and disagreements; a single aggregate accuracy number hides which edit decisions are unsafe.
Recheck the current Gemini video understanding guide when interpreting configuration-specific failures; do not transfer a result between modes or models without a new run.
Timestamp precision
Measure the difference between the returned timestamp and the ground-truth start/end. Define exact, acceptable, and miss windows before scoring. For a split-second edit, an answer within five seconds may still be unusable.
Score both boundary and retrieval. A response may locate the correct scene while missing the exact edit point. Preserve that distinction for editors who need frame-level decisions.
Count accuracy
Compare the action count and inspect whether the near-action was included. Record absolute error and the explanation. A correct number with unsupported reasoning still needs review.
Cross-modal evidence
Check whether the order number comes from audio, transcript, or the visual decoy. Reward an answer only when the number and cited modality match the ground truth. This exposes confident transcript traps.
Unsupported answer
Flag any claim that cannot be traced to a time window or modality. Confidence wording does not replace evidence. An AI video analyzer should be allowed to say it cannot verify a moment.
Question | Ground truth | Static result | Agentic result | Static score | Agentic score | Reviewer note |
|---|---|---|---|---|---|---|
Moment | ___ | ___ | ___ | ___ | ___ | ___ |
Count | 9 | ___ | ___ | ___ | ___ | ___ |
Audio fact | 418 | ___ | ___ | ___ | ___ | ___ |
Anomaly | ___ | ___ | ___ | ___ | ___ | ___ |
Evidence | ___ | ___ | ___ | ___ | ___ | ___ |
Uncertainty | ___ | ___ | ___ | ___ | ___ | ___ |
Google says agentic processing can perform sub-second retrieval, long-video search, anomaly inspection, and dynamic-FPS action analysis. Treat those as capabilities to test, not as your result.
Price misses, not just tokens
Token and API cost are easy to total. Human correction and a bad downstream edit can cost more. Build both a raw and quality-adjusted view.
Token delta
Calculate (static tokens - agentic tokens) / static tokens with the actual receipts. Report input and output separately when available. Do not substitute Google’s up-to 88% benchmark for your result.
Cost delta
Use the current, dated pricing applicable to the recorded model and region. Include feature fees if any; Google’s announcement currently says agentic understanding uses standard Gemini API token pricing with no additional feature fee. Verify that statement before publication.
Correction time
Ask a reviewer to verify every answer and correct misses. Record minutes spent finding the event, rewriting the brief, and documenting uncertainty. A cheap response that takes longer to audit may not be cheaper operationally.
Edit-risk cost
Assign a risk class. A wrong summary sentence may be reversible; deleting the only correct shot, approving a compliance claim, or routing a safety decision is higher impact. Do not convert risk into fake currency if the team has no defensible cost model. Use low/medium/high plus a required reviewer.
Measure | Static | Agentic | Difference |
|---|---|---|---|
Total tokens | ___ | ___ | ___% |
API cost | ___ | ___ | ___% |
Correction minutes | ___ | ___ | ___ |
False negatives | ___ | ___ | ___ |
False positives | ___ | ___ | ___ |
High-risk misses | ___ | ___ | ___ |
Quality-adjusted cost can be expressed as API cost + reviewer time + documented remediation. Keep the inputs visible so the result can be recalculated when pricing or staffing changes.
Route safe jobs and human review
The audit ends with routing, not a winner badge. Map each use case to the level of review justified by your file-specific errors.
Automation-safe
Start with work nobody minds redoing: a rough chapter list, candidate B-roll moments, or a first-pass navigation index. The machine is pointing, not deciding. Keep the source open beside the suggestion, and make sure one missed event won’t erase, approve, or publish anything.
Spot-check
If the planted test passes your tolerance, allow summaries, counts, search results, or draft edit notes into a spot-check queue. A reviewer opens the cited timecode, watches the surrounding seconds, and accepts or rejects the note. Sample an ordinary moment and a hard one. Next week, rotate the questions; otherwise the check quietly becomes a test of the same easy scene.
Human-required
Some jobs stay human. Legal or compliance interpretation, identity-sensitive decisions, safety events, and irreversible deletions need the original footage and a responsible reviewer. So does any answer that arrived without supporting evidence. In this workflow, Gemini analysis is not an APOB feature; it is an outside input that must earn its place in the brief.
Retest trigger
Keep the odd little 20-minute test video. Run it again when the model, processing mode, price, input format, query schema, or source type changes. A new release note is not a regression result. The old file and hidden answer key make the change measurable in an afternoon.
Job | Route | Required evidence | Human sign-off |
|---|---|---|---|
Rough chapter suggestions | Automation-safe after pass | Candidate timestamps | Sample review |
Moment retrieval | Spot-check | Exact window and frame | Editor |
Action count | Spot-check/full review by tolerance | Count definition + window | Reviewer |
Compliance or identity | Human-required | Source plus specialist review | Qualified owner |
Irreversible edit | Human-required | Verified edit decision | Editor/producer |
Once a finding is checked, it can become a scene card in the APOB AI Storyboard, a source note in the APOB AI Video Editor, or a brief for the APOB AI Video Generator. Attach the receipt and the timecode. Moving an unverified answer into a polished creative tool does not make it safer.
Before an AI analysis drives a real cut, ask these six questions of one video you own. Maybe agentic processing saves tokens. Maybe it finds the eight-frame reversal. Maybe it changes nothing. All three are useful results when the receipts remain visible.
Sources
Be the first to like this.





No credit card needed


